

She runs a fleet of agents at TinyFish, where I work now, and she has switched off nearly every approval step the setup offers her. Reversible tasks run start to finish with nobody watching. By the ladder I published a few months ago — Watch, then Verify, then Delegate — she had finished climbing.
Then I watched her kill a run four seconds in.
Nothing had failed. The agent had resolved a source and begun reading it, and something about which source it picked was wrong enough that she stopped everything before a single line of output existed. Not that one. She did not wait to see what it would say. Four seconds was enough.
A few days later, a newer operator sat through a structurally identical run all the way to output before catching the same class of problem. She had more gates enabled, not fewer. Every one fired. She approved through all of them without reading what they were showing her. Lower on my own ladder, and slower to act than the colleague who had removed almost all her guardrails.
I had welded together two things that come apart in practice. Grant the system more latitude, relax scrutiny: a ladder insists those are one act, because climbing is what a ladder does. Experience produces the opposite pairing. An operator who has run a system a thousand times knows which four seconds carry the risk. She can leave the other fifty-six unattended precisely because she is not watching diffusely. She is watching one thing hard, and she will pull the cord on a cue her cautious colleague cannot yet read as a cue.
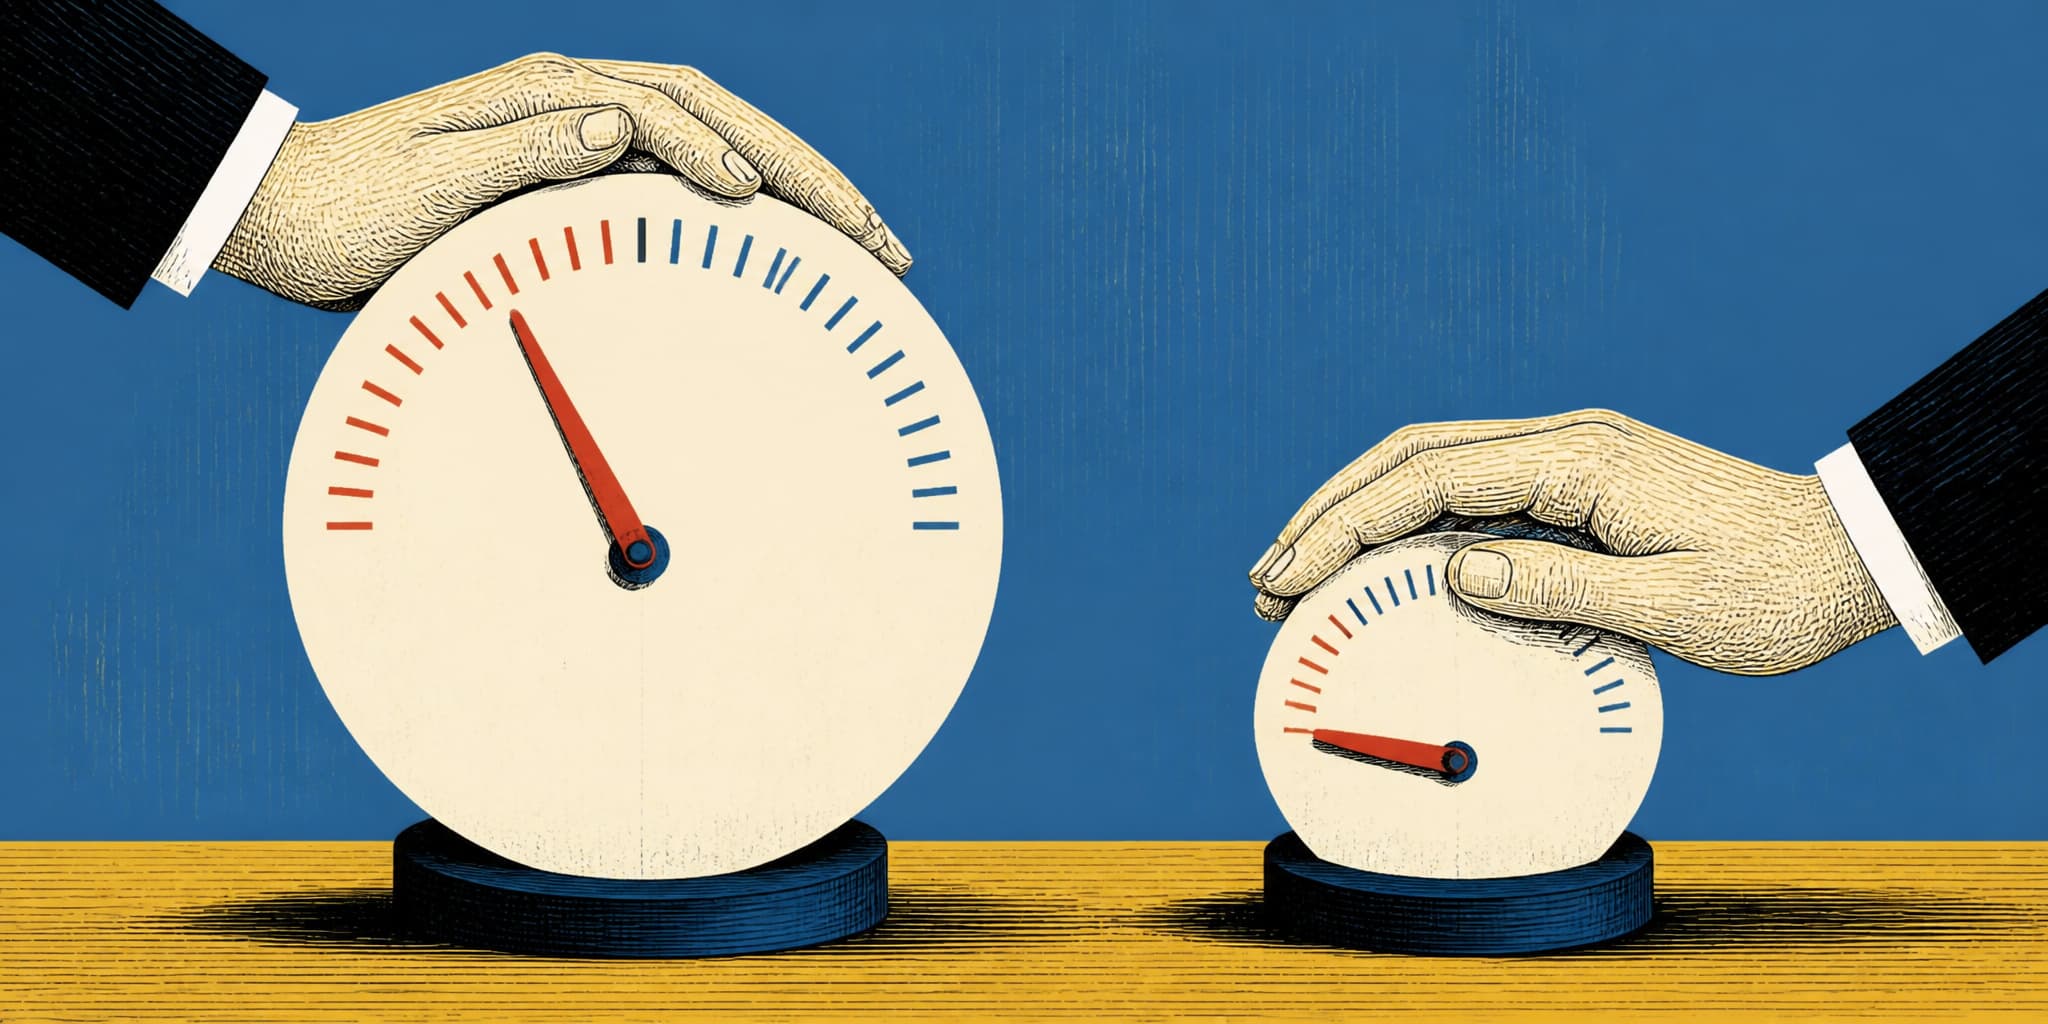
Two settings, then. How much the system may do without asking. How sharply the human reacts when something looks wrong. Autonomy scope and intervention sensitivity. The evidence that they move independently is the cells a ladder says cannot exist. Wide autonomy with a sharp threshold is my expert, and there is no rung for her. Wide autonomy with a dull threshold is the one that hurts you, and the ladder cannot separate it from mastery, because both look like a user who stopped reviewing.
Which means the five handoffs I published were specifying two different things under one label. That essay named the five moments in an agent workflow where trust gets made or lost. Intent-Setting: the system says back what it understood before it moves. In-Progress: the work stays visible instead of vanishing behind a spinner. Output Review: the result is presented so that wrongness is catchable. Decision Gate: a person keeps authority over anything irreversible. Loop Feedback: this run's output becomes the next run's input.
Plot them on two axes instead of one track and the design work sorts itself.
Intent-Setting sets autonomy scope and nothing else. It answers what the agent may do unsupervised. Output Review sets the intervention threshold and nothing else. It answers what evidence would make a person stop. Two decisions, reached by different reasoning, and the ladder quietly couples them. It implies that a scope selector generous enough for an expert should ship alongside a thinner review surface. My operator argues the reverse. Widen her scope and sharpen her review surface, because sharp is the thing she can actually use.
In-Progress is not a rung at all. It is the instrument panel the threshold reads from, which is exactly why one operator can act on it in four seconds and another cannot act on it in sixty. Decision Gate is the single handoff where the axes are forced to meet, because irreversibility collapses them. Loop Feedback is where a mismatch compounds: it feeds the bad output back in as tomorrow's input.
This publication once framed progressive trust as a dial and a switch. Right about granularity. Wrong about the count. There are two dials, and shipping them as one is a defect rather than a simplification.
So the Trust Pattern Library I have been building changes shape. Three consequences, ranked by how much work they cost me.
-
The three-screens-with-progressively-less-chrome illustration is dead. It is the picture a ladder asks for, and it teaches reduced review as the reward for accumulated trust. The index becomes a grid: autonomy scope on one axis, intervention sensitivity on the other, each handoff plotted as a region rather than a point.
-
Every pattern card carries two required fields where the maturity label used to sit. Permitted autonomous action, stated as a scope. Intervention trigger, stated as an observable condition, per state. Not implied by position in a sequence. A card that cannot name the condition that should stop the run is incomplete and does not ship.
-
At least two handoffs get drawn twice. Same handoff, two coordinates. Output Review at wide autonomy with a high intervention threshold, and Output Review at wide autonomy with a low one. Side by side they look nothing alike.
That comparison is the argument.